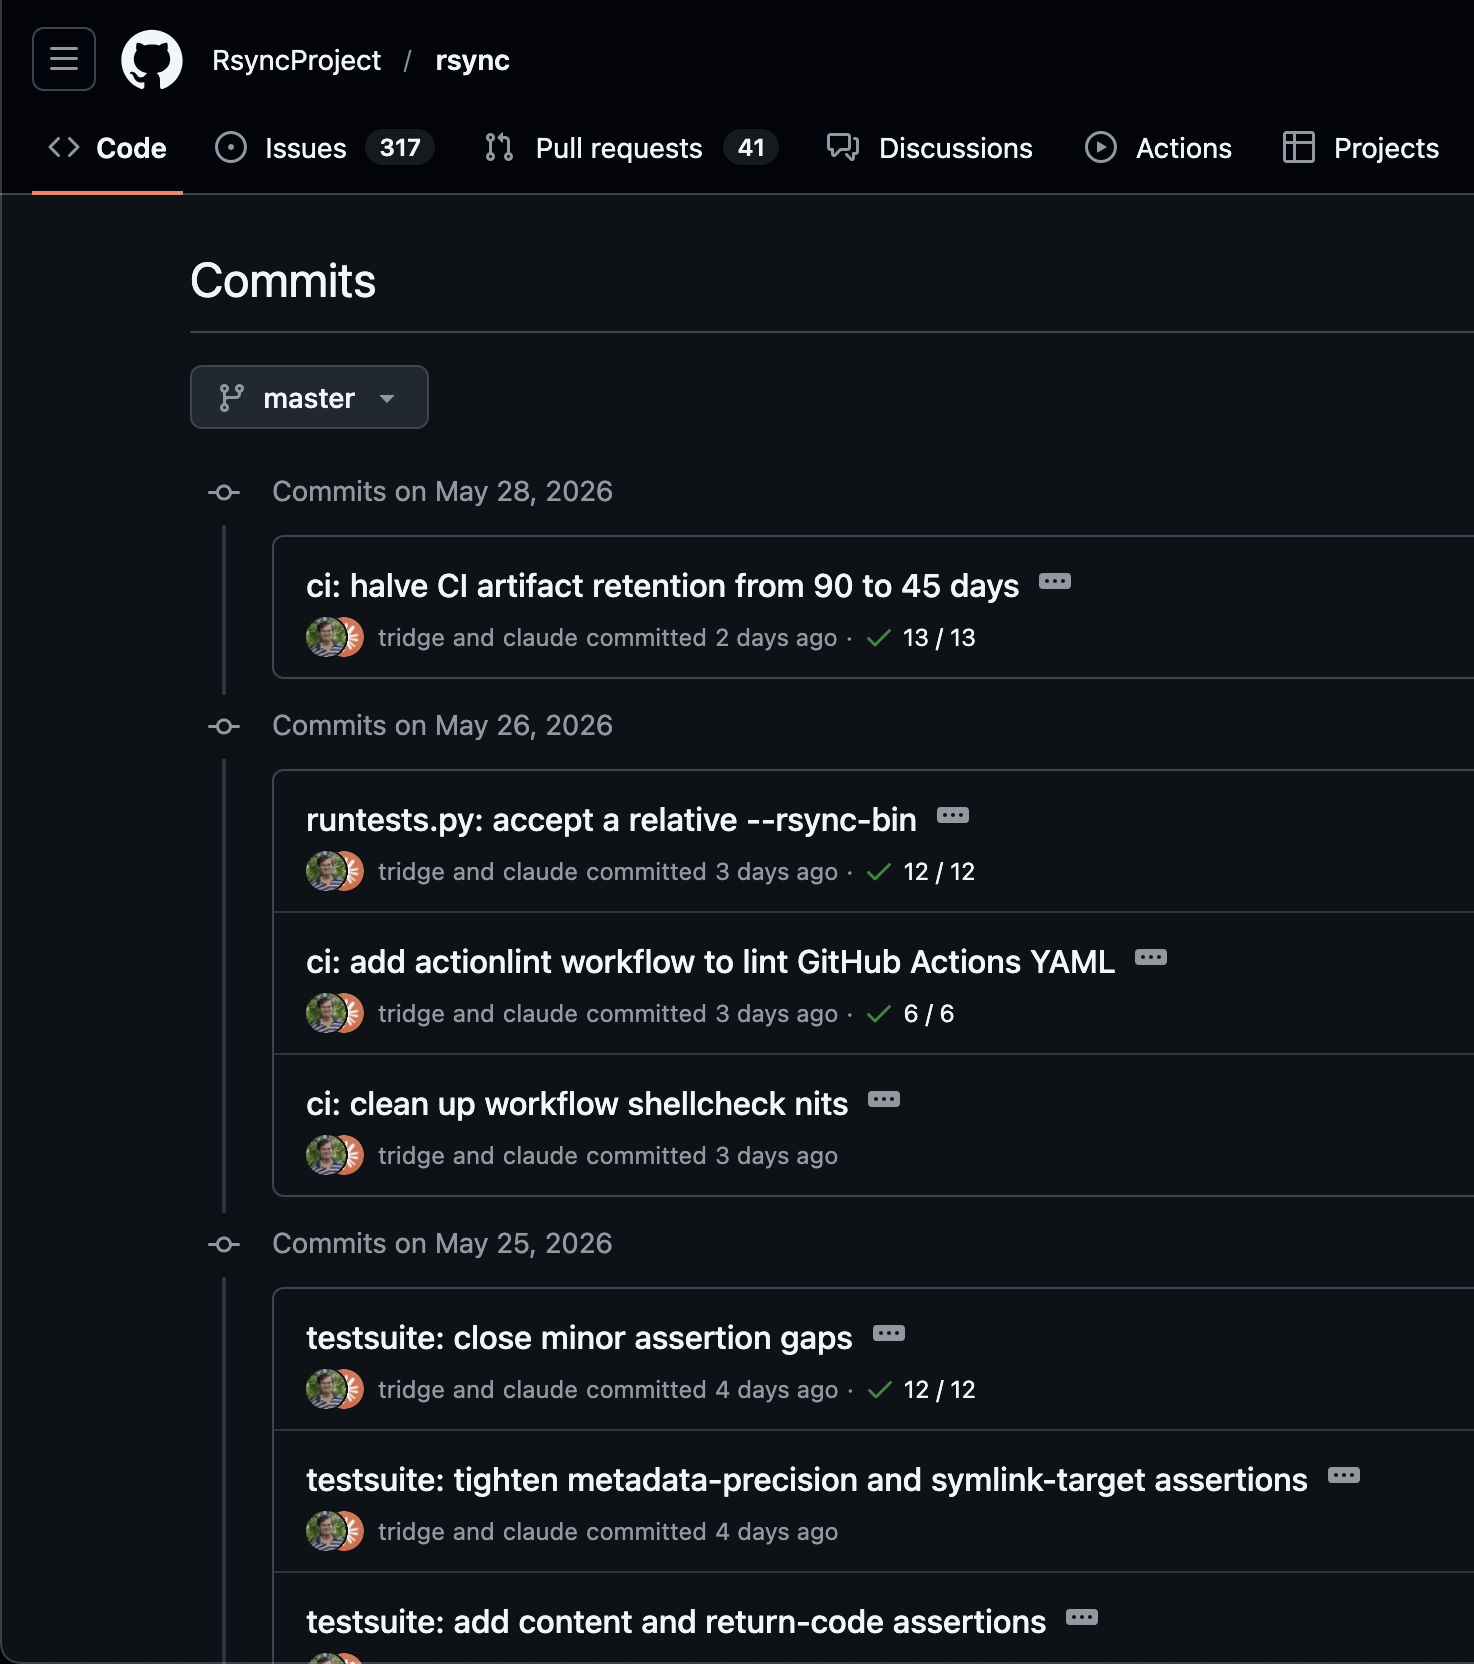

I looked at the rsync commit log and basically every commit since March says “tridge and claude committed.” Andrew Tridgell, the guy who literally invented rsync in 1996. Now hes using a chatbot to write the code and proudly displaying its name right there in the commit.
And before anyone goes “calm down its just a typo fix” no. The recent stuff is the security fixes for 3.4.3. The symlink race CVEs… You know, the exact part where you want an actual human who understands what hes doing, not a machine that spits out code that looks correct but has correctness errors.
Do you get how insane this is? Rsync is the thing holding up basically every backup system on earth. Your NAS uses it. Distro mirrors use it. The server with you grandmas photos uses it. And now the plan is to let a token predictor that can’t even count the amount of letter R’s in “strawberry” write code for it.
“But the tests pass.” The tests pass because the AI probably wrote the tests too you walnut. Its a loop of confident nonsense thats grading its own homework, and the first time it hits an edge case nobody fed it its gonna silently corrupt something and noone notices till the backups are already poisoned.
I’m pinning v3.4.1 and not updating again. If you defend this, dont say nobody warned you when the data loss posts start appearing.
You must log in or # to comment.
To assume the creator of rsync is vibe coding because they used AI is ridiculous.
It’s not.
assume the creator of rsync is vibe coding because they used AI
vibe coding = using AI
using AI = vibe coding
They’re two terms for exactly the same thing, inseparable.
Lot of assumptions as to what’s going on here. All we can say for certain is that Claude is involved in the process somewhere.
I think concern is warranted, but let’s wait for more information before we decide rsync is “cooked”.
But I already had my pitchfork ready!
I think you should keep it ready.
May I interest you in using it against corrupt governments?
If we assume that Claude has free rein, the quality of rsync will fall. Now the real question is: Can we realistically assume that?
What if there is a human in the loop who has decades of experience, is more than qualified to evaluate the quality of the code, spends time reviewing it, finds stupid nonsense and fixes it. You could either fix it manually or tell Claude to fix it, which results in a few more coding and review iterations until the code is good enough. If the human in the loop is a responsible person, I think it’s fair to give them the benefit of the doubt.
Is that too much to ask? Not every application is developed and maintained by a lazy idiot with the programming skills and attention span of a toddler. There are serious and skilled people out there who use LLMs responsibly.
There are serious and skilled people out there who use LLMs responsibly.
There is no “responsible use” for a platform built on the largest form of labor theft ever devised.
largest form of labor theft ever devised
Are we talking of the wheel or fire? Or perhaps a steam engine?
That argument is just plain stupid, while there’s actually real issues with corporate AI shit
No, we’re talking about companies scraping hundreds of millions if not billions of labor hours of output to train their models for the sake of developing software products which they then sell for profit.
Every model that was trained on legally acquired free public data and open source code should be freely publicly available and open source.
Every model that was trained on not legally acquired public data (e.g. Meta’s models) should be taken out of production until all of the lawsuits are concluded, and hopefully the parties responsible are put out of business.
I’m not talking about future, potential labor that AI might replace. I’m talking about the labor which was stolen to produce these models in the first place.
But, please use AI.
“No ethical consumption under capitalism”
This is a tricky argument to make. Living under capitalism means you don’t really have much of a choice in the matter. If you could easily choose not to participate, it would become an ethical decision.
Currently, LLMs don’t really occupy that position, but soon they will. Eventually, choosing not to use an LLM will be like choosing not to use electricity today. You may not like how your electricity was made, but can you realistically choose not to use it? Most people can’t be expected to make such radical decisions based on ethical questions, because doing so would require significant sacrifices. Same with capitalism today.
Today, you can still choose to avoid LLMs, and it won’t involve massive sacrifices on your part. I wonder how long that still holds true. Regardless, I still approve of your argument, because of the trajectory we’re currently on.
You can still get the right results though, especially if you know what you are doing.
Its definitely not ethical though. I guess op meant getting working, safe results by “responsibly”.
Not necessarily fairly sourced results, but rsync is open source, so its code probably also was used this train said LLMs…
proudly displaying its name
I prefer that over hiding the fact they used a LLM. At least I know what to expect when I see that.
deleted by creator
Its a fine opinion, but i think the compiler analogy is wrong on so many leveks, it undermines the point you are trying to make

Great - old vulnerabilities are the best! If you actually forked and maintained it you could survive. But pinning an old version is worse than slop imo
But pinning an old version is worse than slop imo
I dunno.
The slop is likely to introduce a lot of new vulnerabilities and issues.
'Member when Microslop bragged about 30% AI code and then kept pushing broken updates? I 'member.
MS was slop before it was AI slop
I don’t think a long time developer would use AI as anything else than a tool. Understanding what you’re doing with the tool is the key.
Yeah, like, let’s improve the super reliable stuff that works perfectly with gambleware!
Also, this irresponsible behavior is now heresy or something? Like non-opensource code, too.
I’m pinning v3.4.1 and not updating again.
Maybe somebody can fork 3.4.1 into a new program without the slop code and do (real, human-made) updates from there?
And deal with the lack of appreciation and storm of criticism the moment they don’t perform their volunteer work the way a bunch of entitled dicks online feel they should
Sure, someone should fork and keep maintaining this software that’s business critical for the entire world and a potential target to attackers with nation-state resources, just to keep its code AI-free and pure, without getting paid.
Not me, though ;)
And make it in rust!
This post is so needlessly aggressive and assumptive.
Also it’s foss. You f you dont like what the maintainers are doing, fork and move on.
But complaining shows nothing but self entitlement. Let the devs do what they want, or pay them
I think people are entitled to complain. They’re just not entitled to be listened to.
But then there is this knee-jerk raging about stuff. If the guy doesn’t disclose it he’s AN EVIL AI USER who’s hiding it. If he does disclose it he’s AN EVIL AI USER who’s even worse because he must be proud of it. In amongst this nobody has any clue if he’s just used Claude to check his work, do his work for him, or somewhere in between.
For the record, if he is proven to be using AI to code the project then sure, everyone pile on, I’ll join you and he’ll deserve it.
People like the free in free software for cost, not liberty to fork.
yes - God forbid people try to use tools to enable them to get things done faster. If folks worked in software they’d see that LLMs will not be going away there. Folks need to understand that FOSS is not an exception here. They’re welcome to fork and maintain things thanklessly themselves if they dislike it.
I work in software. We recently banned that shit. “It’s not going away” my ass, so far all I’ve seen LLMs do is produce a lot of crap nobody could maintain afterwards while seemingly making the people using it dumber in the process.
Sounds like this could be a blog post. I would really like to read about those experiences. If you have the time, please elaborate.
So do I. You can structure and use the tools responsibly.
Two things I really like using LLMs for right now:
1). Search complex codebases for summaries of “how does this work”. Especially if you are working outside of a project you normally work in, but your code still utilizes it and you want to understand some behavior (or at least know where to look).
2.) PR reviews. I’ve been building a custom skill for awhile now that does a great second pass on PRs. I do my initial review, then sic the LLM on it. It often turns up small things I overlooked that are worth addressing.
Currently, I use LLMs in more of a read-only manner, but I have had success in giving them well-structured easier tickets, if your project has good guidelines and you use the planning mode. You need to have an understanding of where you are working to even utilize these.
I know it’s an unpopular take, because the hive mind wants LLMs to fail SO bad here, but I think there is a usecase for these long-term for B2B software dev.
That said, I generally disagree with the shoving LLMs into things. There are a lot of wasteful examples where companies replace a perfectly good deterministic thing with a token generator and then it gets worse.
What we are seeing right now is a massive backlash on how llms got advertised and subsequent effects (I mean, did you see the price of ram lately?). The thing is, if this got advertised and grew in a responsible manner, all of this would not exist. We would have most people evaluating llms as tools instead of being the anti Christ. It is a shame, but it is what we have. Also, I do think llms will be better in the future, but much smaller than what we have now (and more local as well).
Oh yeah, 100% agree the future is local. I think we’ll have dedicated chips that have specific models burned on to them to run ultra fast and efficiently.
The mainframe style of computing always goes out of vogue as soon as it can because it sucks
God forbid people try to use tools to enable them to get things done faster.
I don’t want my software done faster. I want it done better.
sure - but the unpaid volunteer building your free and open source software wants to go faster so they can spend less of their valuable time on it.
In-general, if you feel this way, lead by example. Fork or contribute but don’t just complain
but the unpaid volunteer building your free and open source software wants to go faster so they can spend less of their valuable time on it.
Well too bad.
I’d rather they give up and stop maintaining it entirely. Then they can spend even less of their valuable time on it. That would be better than filling it with AI slop code.
They are free to work on their project, and you are free to not use their project. No real problem here, right?
You could fork it and start maintaining it yourself. Oh, you won’t? Huh.
It tells me my job is safe, which is nice.
I’ve seen a post on mastodon where some rsync stuff broke already :/
Debian Stable is my last hope.
You Arch fuckers once mocked me for my outdated packages – no more!
I love how confident y’all are that AI isn’t going to affect your coding and you really think you’ll survive in the industry without adjusting how they work.
Even today, it’s already better than most coders at small specialized scoped tasks.
Use the tools when appropriate. This is such a stupid fucking thing to get your undies in a twist over.
But yeah, I’m sure y’all will lead the fork and put in your own time to own it.
I suggest you read up on evidence before calling someone stupid for being cautious. There are studies that prove that open source developers were measured 20% slower when coding with LLMs even though they felt 1.5-2x faster. And we are talking about security sensitive software used by millions of people not ‘small specialized scoped tasks’ like you are in your comment. By the way, there is a huge environmental impact that is being caused by AI bros / big corpos pushing this endless slop onto us. There are protests going on because datacenters are literally poisoning the drinking water, pushing the electricity costs onto the community rather than supplying their own stuff, while adding a handful of jobs to the local economy. Educate yourself, the condescending comment doesnt help any one when the facts arent on your side.
If you don’t trust the guy who “literally invented rsync in 1996” to do right by his project which he has been doing quite all right with for the past 28 years, then I don’t know how to help you. I’d like to put forward an insane idea that he might know what he’s doing and is not vibecoding with a blindfold on and a beer in his hand.
The code is literally all open. Please identify the issues with the LLM generated code.
Sure, its potentially a bit concerning but it also doesn’t automatically make it terrible.
Please identify the issues with the LLM generated code.
Why would the issues be obvious and easy to point out? Most issues with code aren’t. If they were, we wouldn’t have Patch Tuesday, a direct code review would prevent issues from shipping in the first place.
Throwing this out as if it means LLM code is acceptable and ends the argument is ridiculous. Do you have any grasp of how software vulnerabilities are discovered at all?
Are there any actual issues in those commits though? I spot checked a few and they look pretty benign, and don’t really look vibe coded to me. Just because someone uses an AI tool doesn’t mean their work is vibe-coded slop.
A lot of the recent commits are in the test suite, and building test suites, fixtures and harnesses is something AI is fairly decent at if you give it a good prompt (give it the input, expected output, and expected side effects).